0%
Reduction in Search Latency
By improving indexing structures for vector databases, query overhead is virtually eliminated even at extreme scale.
Enhancing vector search performance, embedding management, and semantic retrieval accuracy for large-scale AI applications.
We Built to fix what slows enterprise RAG down: latency and semantic accuracy.
Traditional vector databases are slow and struggle with domain-specific nuances. Our semantic intelligence layer sits directly between your enterprise data and your LLM, restructuring high-dimensional arrays in real-time to guarantee perfect context retrieval.
Infrastructure Health Metrics
Indexora acts as an intelligent optimization layer, drastically reducing query overhead while improving semantic ranking accuracy.
By improving indexing structures for vector databases, query overhead is virtually eliminated even at extreme scale.
Our Query Understanding System interprets user intent, expanding it for near-perfect context matching
Fine-tuning embedding representations to reduce noise in vector space and vastly improve clustering similarities.
Command Center
Monitor vector database performance, fine-tune embeddings, and optimize semantic retrieval in real-time.
Visualize how data moves from raw storage to precise semantics through the Indexora optimization layer.
.svg)
High-dimensional embeddings are ingested directly from Vector DBs via low-latency API streams.
.svg)
The AI engine analyzes noise, compresses vectors dynamically, and expands query semantics.

Optimized context is strictly ranked and delivered directly into the RAG pipeline.

Seamlessly connects with intelligent agents to deliver hallucination-free generation.
Semantic Retrieval Intelligence Layer
Enhances your existing vector databases and RAG pipelines to deliver unmatched contextual relevance and performance.
Storage Efficiency
Improves indexing structures for vector databases. Reduces search latency and query overhead while optimizing the storage efficiency for high-dimensional embeddings.
Contextual Relevance
Improves ranking of retrieved results, enhances contextual relevance of search outputs, and optimizes embedding similarity scoring for precise answers.
AI Semantics
Interprets user queries using AI semantics to automatically expand and refine search intent, drastically improving retrieval precision for LLM applications.
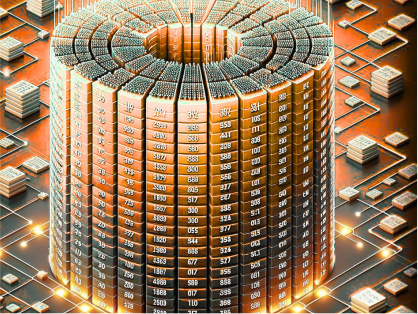
The AI Process
A visualizer showing embedding generation pipelines, vector indexing workflows, and semantic search optimization layers.
Connect Pinecone, Weaviate, Milvus, and enterprise data sources via low-latency API streams.
Connect Pinecone, Weaviate, Milvus, and enterprise data sources via low-latency API streams.
Reduce noise in vector space representations. The AI engine fine-tunes embeddings and compresses vectors.
Reduce noise in vector space representations. The AI engine fine-tunes embeddings and compresses vectors.
Queries are rewritten, intents expanded, and outputs are strictly ranked for maximal relevance.
Queries are rewritten, intents expanded, and outputs are strictly ranked for maximal relevance.
Seamlessly connects with intelligent agents to deliver highly accurate, hallucination-free generation.

Seamlessly connects with intelligent agents to deliver highly accurate, hallucination-free generation.
Monetization & Scaling
Indexora operates on a subscription-based SaaS model with query volume-based pricing, enterprise retrieval licensing, and custom RAG consulting.
API access for vector intelligence services, designed for LLM application developers and small AI engineering teams.
Includes standard embedding optimizations and semantic retrieval APIs.
Subscription-based SaaS model offering full-scale Vector Index Optimization and Embedding Framework fine-tuning.
Best for Enterprise search platforms and knowledge management systems.
Enterprise retrieval optimization licensing and dedicated consulting for complex generative AI systems.
On-premise deployment options and dedicated AI architects for your RAG pipelines.
Need custom RAG optimization consulting or unlimited API access? Leave a note in the contact form.
Enterprise Adoption
Leading machine learning researchers and LLM application developers rely on Indexora to scale their RAG architectures.
“Indexora drastically reduced our search latency. Its intelligent optimization layer allowed us to keep our existing vector databases but improved our retrieval accuracy by over 40% almost instantly.”

Sterling Whitlock
Head of AI, Enterprise Search Platform
The Engineering Team
Indexora was built by a dedicated team of AI infrastructure specialists obsessed with high-dimensional data optimization and large-scale semantic search performance.
Leander Elias
Lead AI Architect
Dr. Elara Vivienne
Machine Learning Researcher
Cassian Theodore
Vector Database Engineer
Matilda Seraphine
Retrieval Scientist
FAQs For AI Engineers
Everything you need to know about how Indexora integrates with your existing RAG ecosystem.
Can't find the answer you're looking for? Please chat to our friendly team.
Get in touchEnterprise Integration
Need custom optimization consulting or unlimited API access? Reach out to our AI engineering team.
Phone
+1 (213) 708-6172Location
600 Wilshire Blvd, Los Angeles, CA 90017, USA